Text and Content Blog: Writing and Editing

Remove Duplicate Lines: Quick Cheat Sheet With 13 Fixes

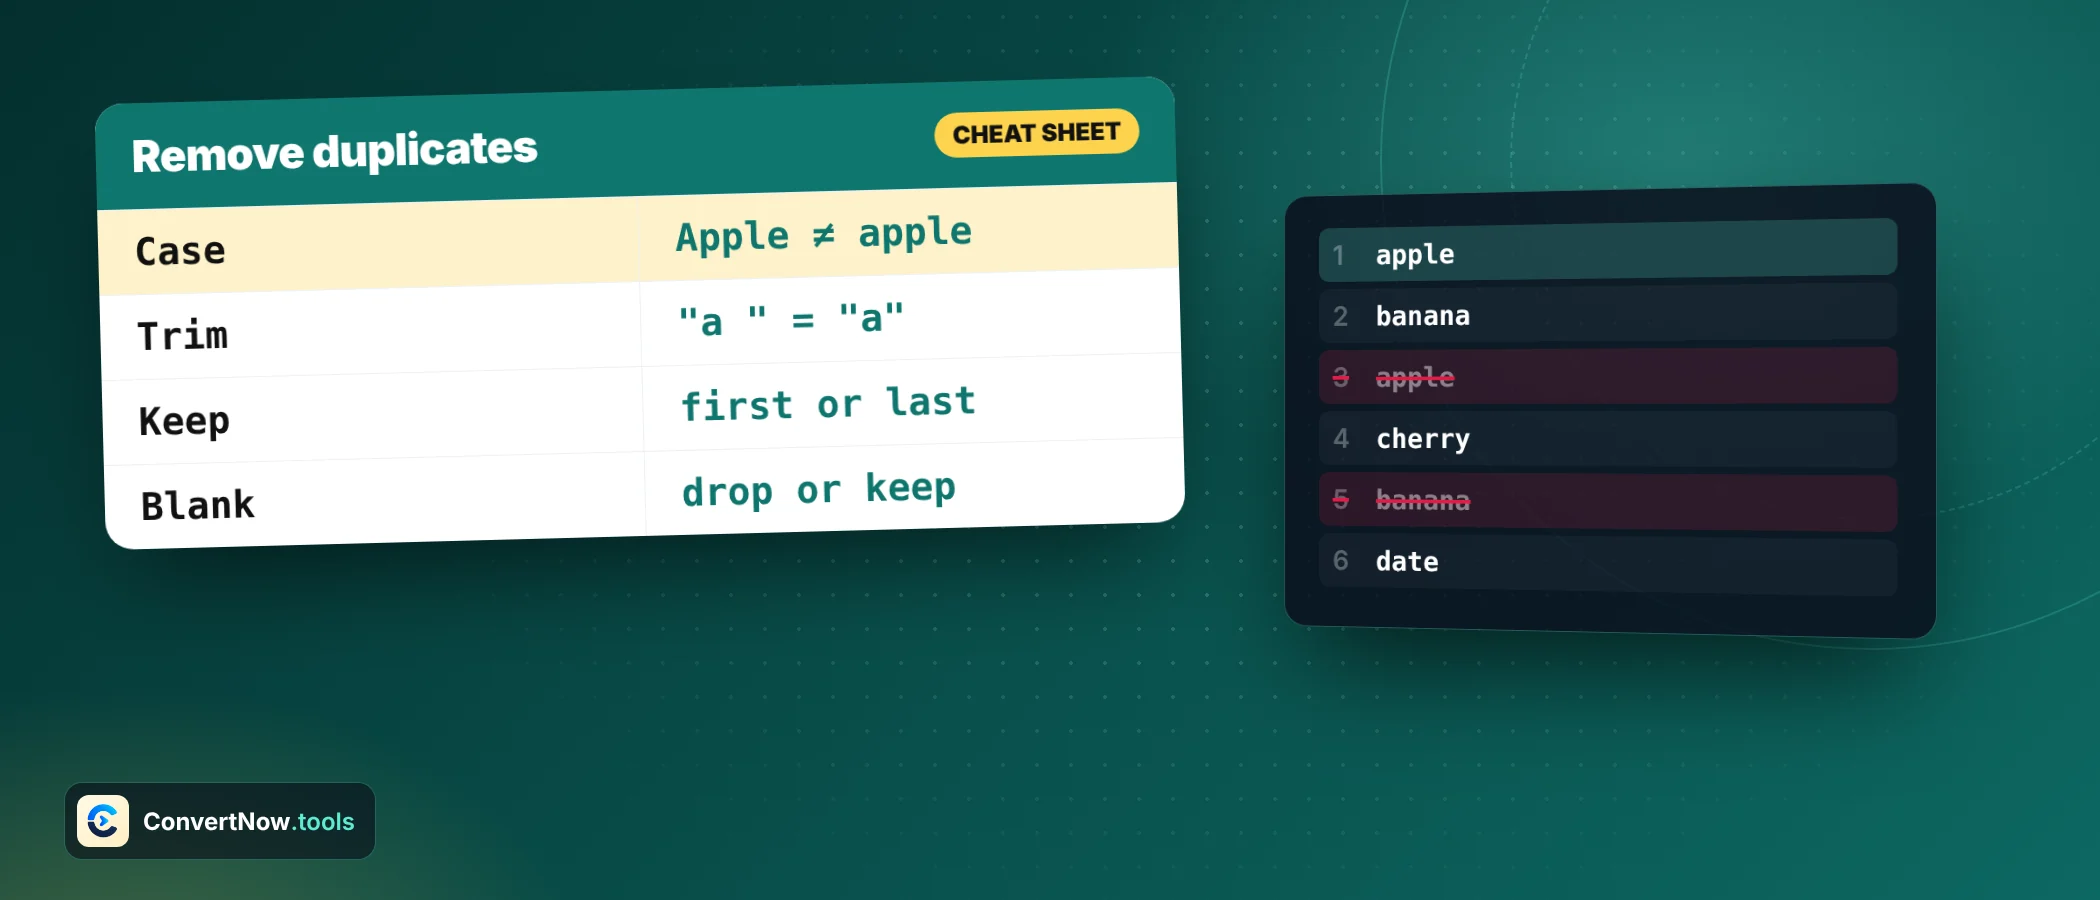
Remove Duplicate Lines: Quick Cheat Sheet With 13 Fixes

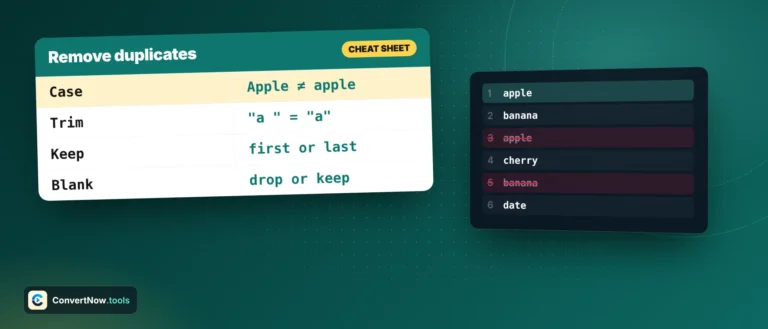
Need to remove duplicate lines fast? This cheat sheet covers the options that matter, one line commands, spreadsheet formulas and common traps.
Keyword Density Mistakes: 9 Easy Fixes That Really Work

Keyword Density Mistakes: 9 Easy Fixes That Really Work

Keyword density mistakes that skew your numbers or read like spam, with 9 clear fixes, worked percentages and a before and after rewrite you can copy.
Sort Lines Alphabetically: 8 Clear Answers, No Surprises

Sort Lines Alphabetically: 8 Clear Answers, No Surprises

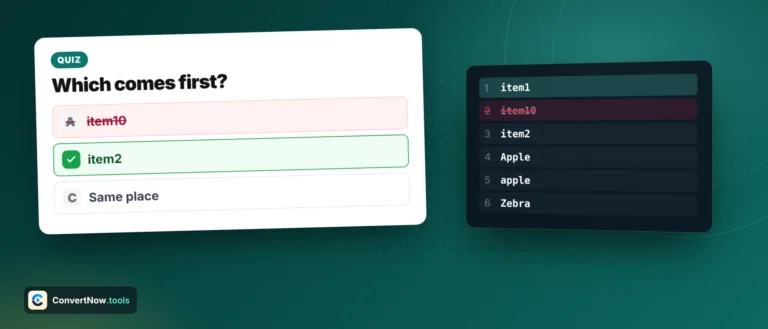
Sort lines alphabetically, by length or in natural number order. Eight clear answers on case, accents, duplicates, ties and random shuffles, with examples.
Compare Two Texts: 6 Easy Ways to Spot Every Change

Compare Two Texts: 6 Easy Ways to Spot Every Change

Compare two texts side by side and see every added, removed or reworded line. Six real tasks by role, with settings, examples and size limits explained.
Reverse Text: 5 Best Methods and Exact Limits to Know

Reverse Text: 5 Best Methods and Exact Limits to Know

Reverse text by characters, words, lines or letters in each word. See when a browser tool is enough, when code is better and where emoji break.
📝 Writing and editing

What the numbers behind your text actually mean

Word counts, readability scores and keyword density all look objective. Each one is a model with opinions baked in, and knowing which opinions helps you decide when to listen and when to ignore the score.

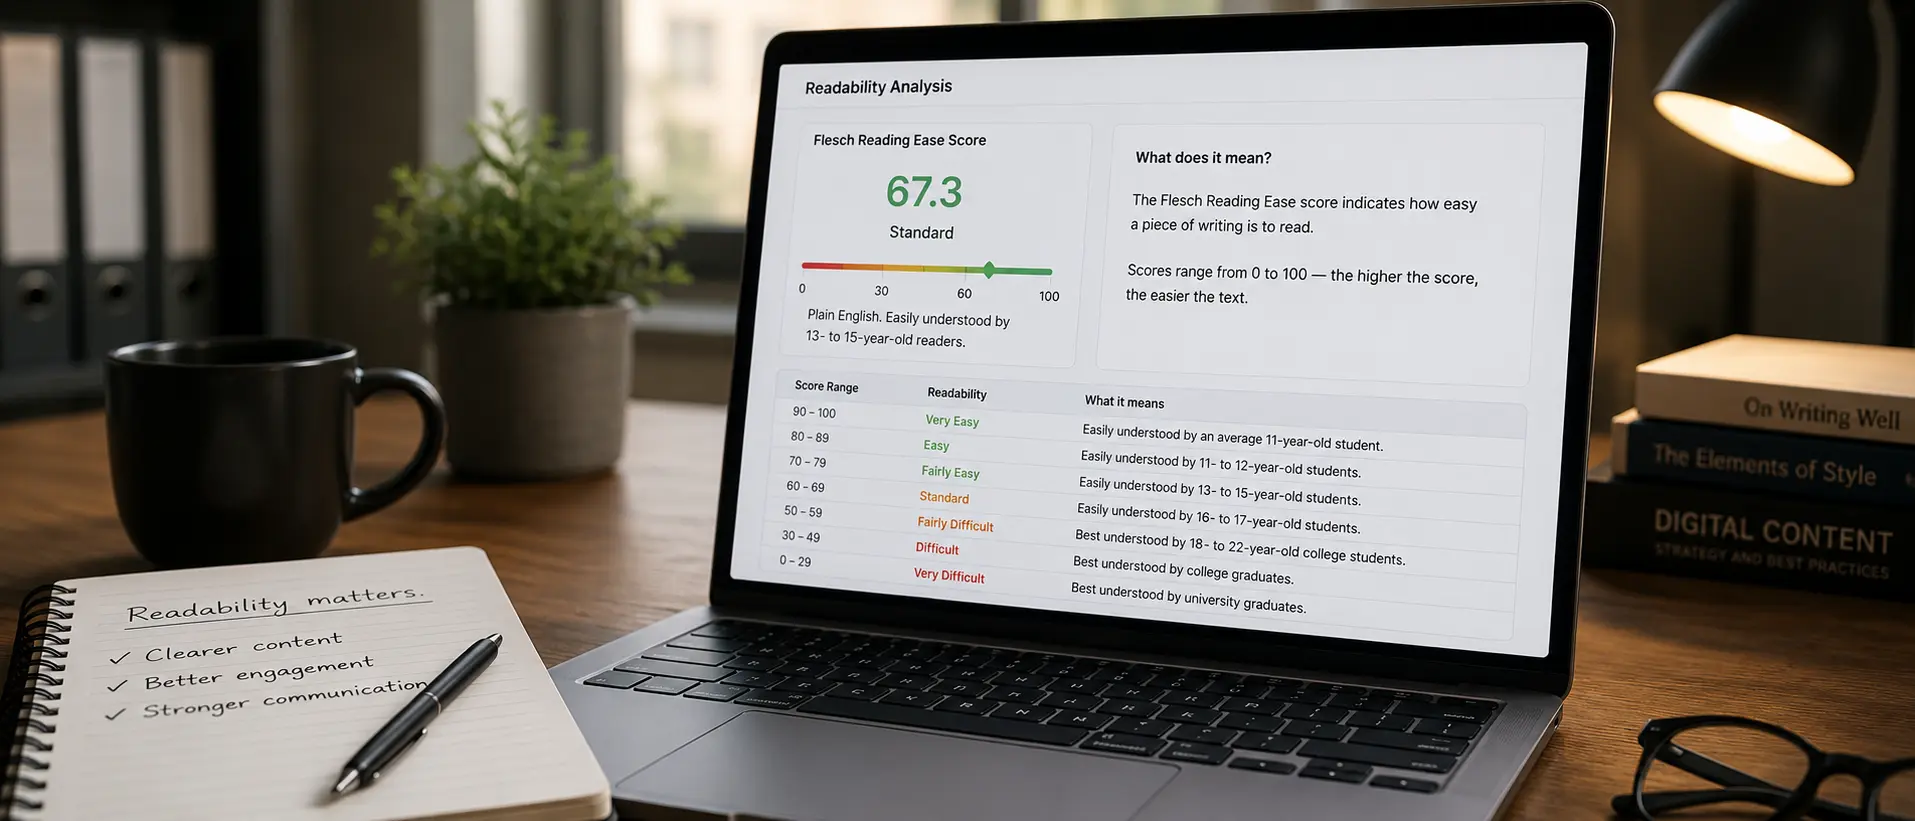
A readability score is a formula counting syllables and sentence lengths. It cannot tell whether a sentence is clear, only whether it is short. That makes it a useful smoke alarm and a terrible editor. These posts explain what Flesch and its relatives measure, where they mislead, and which one suits the kind of writing you actually do.

The same applies to counting. Word count and character count sound identical across tools until you hit hyphenated words, em dashes, emoji or a language that does not put spaces between words. Twitter counts differently from LinkedIn, which counts differently from a word processor. When a limit is hard, the definition matters.

The rest is craft with a mechanical edge: comparing two drafts line by line so a reviewer sees only what changed, stripping duplicates from a list without reordering it, and switching case without destroying acronyms.

What you will find here

  • How readability formulas work and what each one is blind to
  • Why character counts differ between platforms and which one binds
  • Editing workflows that use diffs instead of tracked changes
  • Practical text cleanup for lists, exports and pasted content
FAQ

Questions about text and content blog

Short answers to what readers ask most about this category and the tools behind it.

It depends entirely on the reader. General web writing tends to land well around grade 8 to 10 on Flesch Kincaid, technical documentation sits higher without that being a fault, and a legal notice will score badly no matter how well it is written. Treat the number as a prompt to reread a long sentence, not as a target to optimise.

Because there is no single definition. Tools disagree on hyphenated compounds, numbers, URLs, emoji and text without word spacing. Our Word Counter states its rules on the page, which matters when a limit is enforced by somebody else and you need to know whose count wins.

For reviewing, usually yes. A diff shows what changed between two final states without the noise of every intermediate edit, and it works across formats that have no tracked changes feature at all. Tracked changes are better when the reasoning behind an edit matters as much as the edit.

As a diagnostic, yes. As a target, no. Search engines stopped rewarding a specific percentage a long time ago, but a density check is still the fastest way to notice you have written the same phrase eleven times in nine hundred words, which readers notice even when algorithms do not.

No. Every tool in this category runs in your browser, so unpublished drafts, client copy and anything under embargo stay on your machine. Nothing is transmitted and nothing is stored.

Counting, case conversion, diffing and duplicate removal work with any language and handle unicode correctly. Readability formulas are the exception, since they were calibrated on English and their syllable counting does not transfer reliably to other languages.